
Roundup
September 9, 2026 · 14 min read
Best Job Posting APIs in 2026: 8 Tested and Compared
Job listings as JSON without scraping LinkedIn, Indeed, or thousands of career sites. We ran the same five job searches through 8 job posting APIs, read each provider's published pricing, and worked out what 1,000 jobs cost on each one.

Adam Ben-Ayoun
CTO, OpenWeb Ninja
Jobs API · JSearch · Python · API Comparison
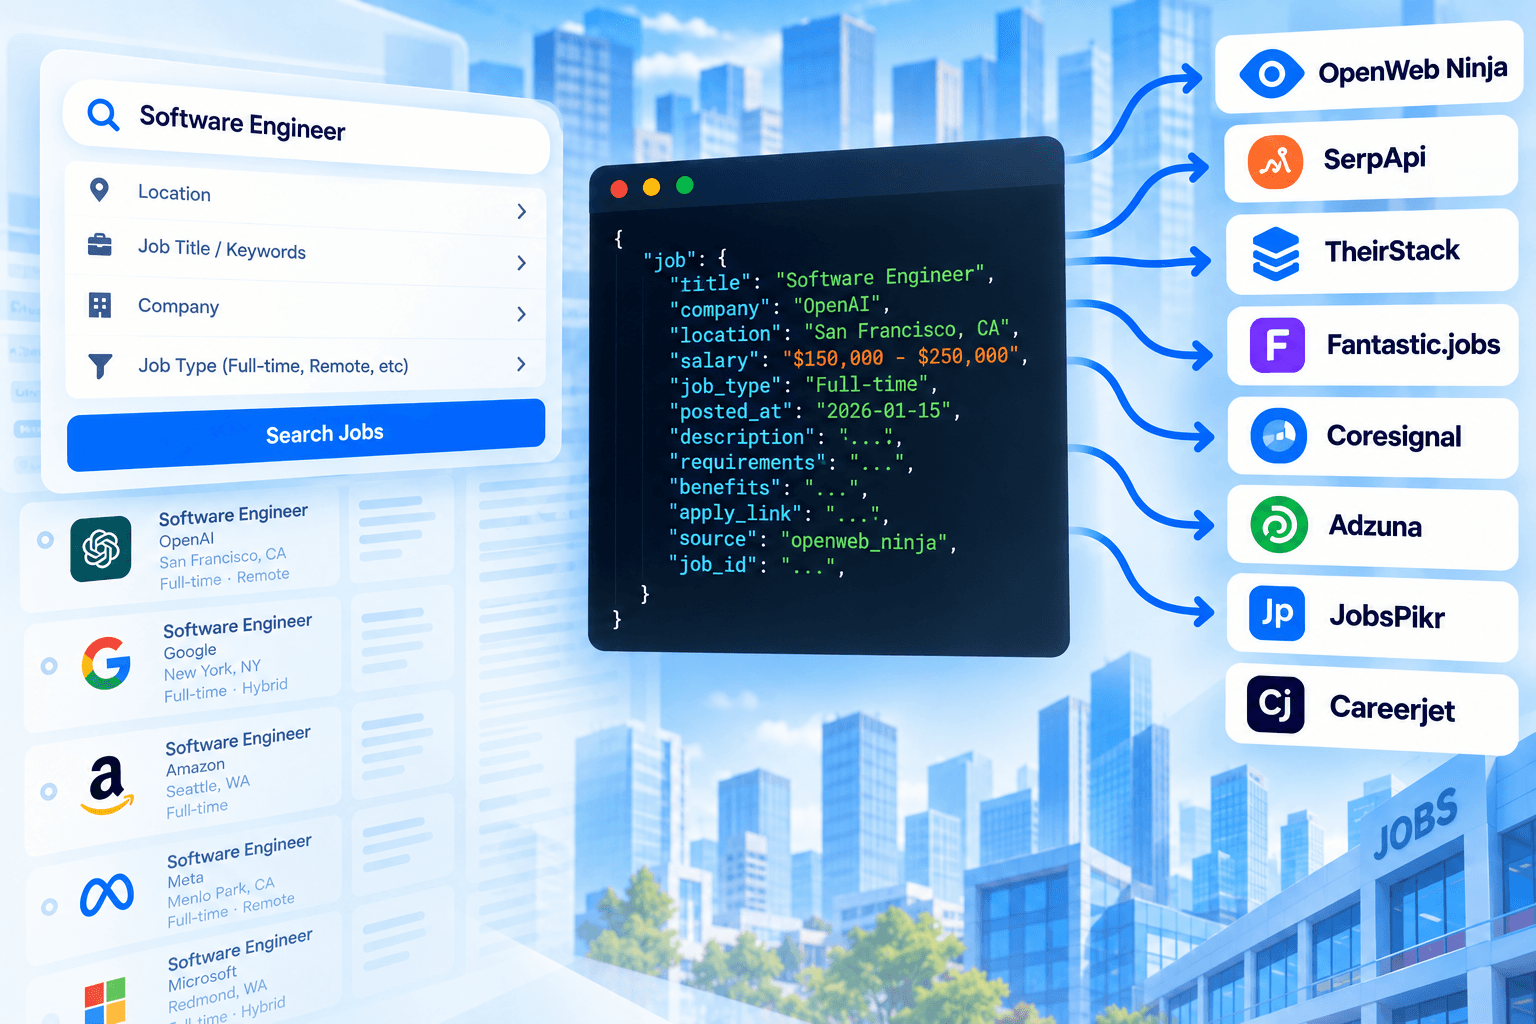
Quick Answer: Best Job Posting APIs at a Glance
Tested September 9, 2026; prices re-checked October 4. "Per 1K jobs" is the entry paid plan, with the two Google for Jobs APIs converted at 10 jobs per request.
| API | Best for | Entry plan | Per 1K jobs | Free tier | Job endpoints |
|---|---|---|---|---|---|
| OpenWeb Ninja JSearch | Live Google for Jobs results, cheapest per job | $25 / 10,000 requests | $0.25 | 200 requests/mo | Search, job details, estimated salary |
| SerpApi | Same Google results, if you already use SerpApi | $25 / 1,000 searches | $2.50 | 250 searches/mo | Jobs search; the listing engine returns ratings at best |
| TheirStack | Tech-stack and company filters for sales intel | $49 / 1,500 credits | $32.67 | 200 credits/mo | Job search (POST), plus webhooks for new and closed postings |
| Fantastic.jobs | Hourly ATS feed, 1,000 jobs per call | $95 / 20,000 jobs | $4.75 | 7-day trial | Active ATS jobs, active job-board jobs, expired, modified |
| Coresignal | Biggest archive, free search, company data | $49 / 2,500 credits | $19.60 | 7-day trial | Search (free), collect |
| Adzuna | Free key with salary stats, 19 countries | Free | $0 | 2,500 requests/mo | Search, categories, salary histogram, top companies, geodata, salary history |
| JobsPikr | Global archive with a resumable cursor feed | $79 / 1,000 credits | $79.00 | 7-day trial | Search, expired jobs, aggregation, location autocomplete |
| Careerjet | Publishers showing Careerjet listings | Free (revenue share) | $0 | Publisher key | One query endpoint |
Looking for LinkedIn, Indeed, or Glassdoor? None of them has an open API. Details below.
How We Evaluated
- What we tested: the same five searches on every API: software engineer in Chicago, registered nurse in Houston, data analyst in New York, marketing manager in Austin, and truck driver in Dallas. One request each, 10 results where the API allows it. The software engineer search is the one shown in each provider's code and response blocks.
- Lookups by ID: where they exist, JSearch job-details and Coresignal collect, plus one JSearch salary estimate and one Adzuna salary histogram.
- Pricing: every number was read from the provider's own pricing page, in a real browser where the page renders prices with JavaScript. Monthly billing unless stated.
- Unit conversion: requests, credits, and records were converted to cost per 1,000 jobs, counting 10 jobs per request for the two Google for Jobs APIs.
- Code and responses: every code block was executed as printed, with only the credentials replaced, and every response block is trimmed from the JSON that call returned. Six providers were tested on free or trial accounts created for this article, SerpApi on an existing account.
- Response time: the five searches, once each, from one machine in the same session. We report the median. It is a smoke test, not a benchmark.
- Scope: US searches in English. Coverage elsewhere varies by provider (Adzuna lists 19 countries, Careerjet 68 locales) and was not tested.
- Order: by how many readers we expect each to fit, weighing cost, fields per record, freshness, filters, and free tier, not strictly by price.
We build one of these APIs, so read the JSearch section with that in mind. The competitor sections are as flattering as the published numbers allow.
Same Query, Seven Different Top Results
"Software engineer" in Chicago, IL, first result from each API.
| API | First result | Posted | Results / total |
|---|---|---|---|
| JSearch | Software Engineer - Entry Level 2027, Belvedere Trading (via LinkedIn) | Aug 29 | 10 / n.a. |
| SerpApi | Same job as JSearch | Aug 29 | 10 / n.a. |
| TheirStack | Software Engineer Intern, Cboe Global Markets | Sep 8 | 10 / 520 (30 days) |
| Fantastic.jobs | Senior Software Engineer, Publicis Groupe (via iCIMS) | Sep 8 | 10 / n.a. (7 days) |
| Coresignal | Software Developer, Siemens | Dec 18, 2025 | 1,000 IDs / 107,099 |
| Adzuna | Software Engineer, Motorola Solutions | Sep 3 | 10 / 2,096 |
| JobsPikr | Senior Security Software Engineer, Moveworks (via Experteer) | Aug 9 | 10 / 1,146 |
| Careerjet | Sr Software Engineer Low Latency, Software Guidance & Assistance | Aug 14 | 20 / 915 |
JSearch and SerpApi both read Google for Jobs, so they agree (on four of the five searches). The other six run their own indexes and their own ranking, so the same query gives six different top jobs, from posted yesterday (TheirStack, Fantastic.jobs) to posted last December (Coresignal, which ranks by relevance, not date). Totals range from 520 to 107,099 depending on how deep the archive goes. Filter by date and sort explicitly if you want reproducible lists.
OpenWeb Ninja JSearch
this siteBest for: live Google for Jobs results at the lowest cost per job, with job details and salary estimates on the same key
JSearch queries Google for Jobs in real time, which already aggregates LinkedIn, Indeed, Glassdoor, ZipRecruiter, and company career pages. You get search, job-details, and estimated-salary endpoints, with filters for date posted, remote, employment type, and experience. Billing is per request (a page of up to 10 jobs). Free is 200 requests a month; Pro is $25 for 10,000, Ultra $75 for 50,000, Mega $150 for 200,000, and scale plans go to $2,000 for 5 million. That is $0.25 per 1,000 jobs at Pro and $0.04 at the top.
Python example: job search
# openwebninja_jobs_search.py
import requests
response = requests.get(
"https://api.openwebninja.com/jsearch/search",
headers={"x-api-key": "YOUR_API_KEY"},
params={"query": "software engineer jobs in Chicago, IL", "page": 1, "num_pages": 1, "country": "us", "date_posted": "all"}
)
jobs = response.json()["data"]
first = jobs[0]
print(len(jobs), first["job_title"], first["employer_name"], first["job_location"], first["job_publisher"], first["job_posted_at"])
Response (trimmed)
{
"status": "OK",
"data": [{
"job_title": "Software Engineer - Entry Level 2027",
"employer_name": "Belvedere Trading, LLC",
"employer_website": "https://www.belvederetrading.com",
"job_publisher": "LinkedIn",
"job_employment_type": "Full-time",
"job_apply_link": "https://www.linkedin.com/jobs/view/software-engineer-entry-level-2027-at-belvedere-trading-llc-4449213283",
"apply_options": [{"publisher": "LinkedIn", "apply_link": "https://www.linkedin.com/jobs/view/...", "is_direct": false}],
"job_description": "Belvedere Trading is a leading proprietary trading firm proudly headquartered in downtown Chicago...",
"job_is_remote": false,
"job_posted_at": "11 days ago",
"job_posted_at_datetime_utc": "2026-08-29T00:00:00.000Z",
"job_location": "Chicago, IL",
"job_latitude": 41.88325,
"job_longitude": -87.6323879,
"job_min_salary": null,
"job_max_salary": null
}, ...]
}
10 jobs, 35 fields each: full description, every apply link, structured location with coordinates, salary when stated. Job-details adds 18 more (seniority, work arrangement, required technologies, visa sponsorship, and so on). The estimated-salary endpoint returned a $159,551 median for software engineers in Chicago from 13,750 Glassdoor salaries. Median 6.3 s per search: it is a live Google query, and it shows.
Pros
- +Cheapest paid source by far: $0.25 per 1,000 jobs, $0.04 at scale
- +Full description and every apply link in the search result, plus details and salary endpoints
- +Date, remote, and employment-type filters, and 50+ other APIs on the same key
Cons
- -Slowest in the test: 6.3 s median, one 13 s outlier
- -No total count, no history, and ranking is Google's, so no sort by date
- -No company or technology enrichment on the search result
SerpApi Google Jobs API
Best for: teams already on SerpApi who want Google for Jobs on the same account
Same Google for Jobs index, one search per page of 10. Filters are thin: Google deprecated the chips and ltype parameters, so there is no date or remote filter, and the old google_jobs_listing details engine now returns ratings at best. Free is 250 searches a month; Starter is $25 for 1,000, Developer $75 for 5,000, Production $150 for 15,000, and the ladder runs to 54 million searches for $106,050. That is $2.50 per 1,000 jobs at Starter.
Python example: job search
# serpapi_jobs_search.py
import serpapi
client = serpapi.Client(api_key="YOUR_API_KEY")
results = client.search({
"engine": "google_jobs",
"q": "software engineer",
"location": "Chicago, Illinois, United States",
"gl": "us",
"hl": "en"
})
jobs = results["jobs_results"]
first = jobs[0]
print(len(jobs), first["title"], first["company_name"], first["location"], first["via"], first.get("detected_extensions", {}).get("posted_at"))
Response (trimmed)
{
"jobs_results": [{
"title": "Software Engineer - Entry Level 2027",
"company_name": "Belvedere Trading, LLC",
"location": "Chicago, IL",
"via": "LinkedIn",
"detected_extensions": {"posted_at": "11 days ago", "schedule_type": "Full-time"},
"description": "Belvedere Trading is a leading proprietary trading firm proudly headquartered in downtown Chicago...",
"job_highlights": [{"title": "Qualifications", "items": [...]}, ...],
"apply_options": [{"title": "LinkedIn", "link": "https://www.linkedin.com/jobs/view/..."}, ...],
"job_id": "eyJqb2JfdGl0bGUiOiJTb2Z0d2FyZSBFbmdpbmVlciAtIEVudHJ5IExldmVsIDIwMjciLCJjb21wYW55X25hbWUiOi..."
}, ...],
"serpapi_pagination": {"next_page_token": "..."}
}
Same first job as JSearch, 14 fields instead of 35: no structured city or coordinates, no salary numbers, posting date only as "11 days ago", and detected_extensions is optional: on a later re-run, 8 of 10 jobs had none, hence the .get(). Median 1.7 s, but anywhere from 0.3 (cached) to 8.2 s.
Pros
- +Same Google for Jobs coverage, one account for dozens of engines
- +Only successful searches are billed; cached repeats are fast
Cons
- -$2.50 per 1,000 jobs, ten times JSearch for the same results
- -No date, remote, or employment-type filter, and no working details or salary endpoint
TheirStack Job Postings API
Best for: sales and market intelligence teams filtering jobs by technology and company
A job database built for hiring signals. One POST /v1/jobs/search with array filters for title, description regex, country, location, workplace type, seniority, technology, company, and salary. Every query needs a date bound or a company filter, and locations must be GeoNames objects (a plain "Chicago" returns a 422). One credit per job returned. Free is 200 credits a month; paid starts at $49 for 1,500 credits and runs to 5 million for $5,500, with unused credits rolling over 12 months.
Python example: job search
# theirstack_jobs_search.py
import requests
response = requests.post(
"https://api.theirstack.com/v1/jobs/search",
headers={"Authorization": "Bearer YOUR_API_KEY", "Content-Type": "application/json"},
json={
"job_title_or": ["software engineer"],
"job_location_or": [{"id": 4887398}], # GeoNames id for Chicago
"job_country_code_or": ["US"],
"posted_at_max_age_days": 30,
"limit": 10,
"page": 0,
"include_total_results": True
}
)
data = response.json()
first = data["data"][0]
print(data["metadata"]["total_results"], len(data["data"]), first["job_title"], first["company"], first["location"], first["date_posted"], first["salary_string"])
Response (trimmed)
{
"metadata": {"total_results": 520, "total_companies": 271},
"data": [{
"job_title": "Software Engineer Intern",
"company": "Cboe Global Markets",
"url": "https://careers.cboe.com/us/en/job/R-4654/Software-Engineer-Intern",
"date_posted": "2026-09-08",
"location": "Chicago, IL",
"remote": false,
"salary_string": "$22 - $42 an hour",
"min_annual_salary_usd": 45760.0,
"max_annual_salary_usd": 87360.0,
"seniority": "junior",
"technology_slugs": ["python", "django", "javascript", "postgresql", ...],
"company_object": {"name": "Cboe Global Markets", "industry": "...", "employee_count": ..., ... 45 keys}
}, ...]
}
48 fields per job: salary normalised to annual USD, seniority, remote flags, detected technologies, and a 45-key company object with headcount, industry, funding, and revenue. Freshest first result in the test, tied with Fantastic.jobs. Median 3.4 s.
Pros
- +Technology detection and full company data on every job, plus webhooks for new and closed postings
- +Free plan renews monthly; paid credits roll over 12 months
Cons
- -$32.67 per 1,000 jobs at entry, still $1.10 at 5 million
- -GeoNames location objects and a mandatory date or company filter on every query
Fantastic.jobs API
Best for: an hourly feed of new ATS and career-site postings, up to 1,000 jobs per call
A feed more than a search engine. /active-ats covers 200k+ career sites on 55 applicant tracking systems, /active-jb covers LinkedIn, Wellfound, and Y Combinator. A time_frame (1h, 24h, 7d, 6m) is required, limit goes to 1,000, and the AI-derived fields (work arrangement, experience level, visa sponsorship) double as filters. Two counters are billed, jobs returned and API requests. The 7-day trial is 500 jobs and 50 requests a week; Starter-20k is $95 for 20,000 jobs, and plans run to Pro-500k at $900 for 500,000 with $0.0018 per job over. The old RapidAPI listings point here since August 2026.
Python example: new jobs in the last 7 days
# fantasticjobs_jobs_search.py
import requests
response = requests.get(
"https://data.fantastic.jobs/v1/active-ats",
headers={"Authorization": "Bearer YOUR_API_KEY"},
params={
"time_frame": "7d",
"title": "software engineer",
"location": "Chicago",
"limit": 10,
"description_format": "text",
"include_basic_organization_details": "true"
}
)
jobs = response.json()
first = jobs[0]
print(len(jobs), response.headers["x-rapidapi-billing"], first["title"], first["organization"], first["locations_derived"], first["date_posted"], first["source"])
Response (trimmed)
[{
"title": "Senior Software Engineer",
"organization": "Publicis Groupe Holdings B.V",
"date_posted": "2026-09-08T21:33:02.742",
"url": "https://employees-publicisgroupe.icims.com/jobs/154525/senior-software-engineer/job",
"source": "icims",
"locations_derived": ["Chicago, Illinois, United States"],
"employment_type": ["FULL_TIME"],
"salary": null,
"ai_salary_min_value": 88900,
"ai_salary_max_value": 165100,
"ai_experience_level": "5-10",
"ai_work_arrangement": "On-site",
"ai_key_skills": ["Java", "AWS", "Spring Framework", ...],
"org_linkedin_industry": "Information Services",
"description_text": "..."
}, ...]
71 fields, the richest record in the test, but note the ai_ prefix: this posting stated no salary, so the $88,900 to $165,100 range is an estimate, and so are the skills and experience level. Median 1.0 s. Because a time window is mandatory, 6 months back is the ceiling.
Pros
- +Richest record (71 fields) and up to 1,000 jobs per request
- +Cheapest database at entry ($4.75 per 1,000), hourly refresh, free expired and modified endpoints
Cons
- -Tight trial (50 requests a week) and request caps on paid plans too
- -Salary, skills, and seniority are AI estimates on most records; no archive beyond 6 months
Coresignal Multi-source Jobs API
Best for: the largest archive, free search, and one deduplicated record per job across sources
Two steps: search (Elasticsearch DSL, free, returns up to 1,000 matching IDs plus a total in a header), then collect a record for one credit. The Multi-source API merges the same posting from LinkedIn, Indeed, SimplyHired, Adzuna, and others into one record with a per-source status list. Coresignal claims 482M+ postings and 6+ years of history, rechecked daily. The 7-day trial is 2,000 credits (business email needed); Mini is $49 for 2,500 credits, up to Elite at $5,000 for 10 million. That is $19.60 per 1,000 jobs at entry and $0.50 at the top, the cheapest database at volume.
Python example: search (free), then collect one record (1 credit)
# coresignal_jobs_search.py
import requests
headers = {"apikey": "YOUR_API_KEY", "Content-Type": "application/json"}
# 1. Search is free and returns matching job IDs (up to 1,000 per page)
search = requests.post(
"https://api.coresignal.com/cdapi/v2/job_multi_source/search/es_dsl",
headers=headers,
json={"query": {"bool": {"must": [
{"match": {"title": "software engineer"}},
{"match": {"location": "Chicago"}}
]}}}
)
ids = search.json()
print(search.headers["x-total-results"], "matches;", len(ids), "ids on this page")
# 2. Collect one full record (1 credit)
job = requests.get(f"https://api.coresignal.com/cdapi/v2/job_multi_source/collect/{ids[0]}", headers=headers).json()
print(job["title"], job["company_name"], job["location"], job["date_posted"], [s["source"] for s in job["job_sources"]])
Response (collect, trimmed)
{
"title": "Software Developer",
"company_name": "Siemens",
"location": "Chicago, IL",
"date_posted": "2025-12-18 06:00:00",
"updated_at": "2026-09-08 23:59:44",
"seniority": "Mid-Senior level",
"accepts_remote": false,
"job_sources": [{"source": "simplyhired", "status": "inactive"}, {"source": "adzuna", "status": "active"}, {"source": "indeed", ...}, {"source": "linkedin", ...}, ... 15 entries],
"salary": [{"min_value": 159459.0, "max_value": 184926.0, "currency": "USD", "source": "linkedin"}, {"source": "indeed", ...}, ...],
"company_industry": "Automation Machinery Manufacturing",
"company_employees_count": 278571,
"company_hq_location": "Munich, Germany",
"description": "..."
}
62 fields: 15 source listings with active, inactive, or deleted flags, four salary readings from different boards, and company firmographics down to HQ and last funding round. The catch is ranking: the first hit was a December 2025 posting, because search matches text, not recency. Add a date range and sort. Search median 2.3 s, collect 0.15 s.
Pros
- +Search and counting are free; you pay only for records you collect
- +Deduplicated across sources, with firmographics and funding on the same record
Cons
- -Two calls per job and $19.60 per 1,000 at the entry plan
- -Default ordering surfaces months-old postings; freshness is a daily recheck
Adzuna API
Best for: a free key with salary statistics across 19 countries, if snippets and attribution are fine
Adzuna opens its own job index through a free developer API: search, categories, salary histogram, top companies, geodata, and salary history, for 19 countries. Filters cover keywords, location and distance, max days old, category, salary range, contract type, and sort by date or salary; there is no remote filter, descriptions are snippets, and pages cap at 50. There is no price list. Default limits are 25 requests a minute, 250 a day, and 2,500 a month, with a General access tier (500,000 a month) available on request. Displayed ads must carry "Jobs by Adzuna", and the terms permit commercial use "subject to a 14 day trial period", so a commercial product will most likely need an agreement with Adzuna.
Python example: job search
# adzuna_jobs_search.py
import requests
response = requests.get(
"https://api.adzuna.com/v1/api/jobs/us/search/1",
params={
"app_id": "YOUR_APP_ID",
"app_key": "YOUR_APP_KEY",
"what": "software engineer",
"where": "Chicago, IL",
"results_per_page": 10,
"content-type": "application/json"
}
)
data = response.json()
first = data["results"][0]
print(data["count"], len(data["results"]), first["title"], first["company"]["display_name"], first["location"]["display_name"], first["created"])
Response (trimmed)
{
"count": 2096,
"mean": 146954.12,
"results": [{
"title": "Software Engineer",
"company": {"display_name": "Motorola Solutions"},
"location": {"display_name": "Chicago, Cook County", "area": ["US", "Illinois", "Cook County", "Chicago"]},
"category": {"tag": "it-jobs", "label": "IT Jobs"},
"created": "2026-09-03T00:51:25Z",
"salary_min": 121798.12,
"salary_max": 121798.12,
"salary_is_predicted": "1",
"description": "Company Overview At Motorola Solutions, we believe that everything starts with our people...",
"redirect_url": "https://www.adzuna.com/land/ad/5868286340?..."
}, ...]
}
13 fields, with a total count and mean salary in the envelope. The salary here is Adzuna's own prediction (see the flag), the description is a snippet, and links go to Adzuna landing pages. The histogram endpoint is the useful extra: for software engineers in Illinois it returned seven salary buckets from $20,000 to $140,000 across 1,223 postings, 575 of them in the top bucket. Median 0.5 s.
Pros
- +Free, instant key, 19 countries, and aggregate endpoints (salary histogram, history, top companies)
- +Half-second responses with a total count on every search
Cons
- -Snippets instead of descriptions, redirect links, and mandatory attribution
- -No remote filter, no lookup by ID, and predicted salaries need filtering out
JobsPikr API
Best for: a global, multi-language archive with a cursor feed you can resume
Four endpoints under api.jobspikr.com/v2: search, expired jobs, aggregation, and location autocomplete, all taking Elasticsearch-style JSON, 10 to 100 records a page, and a cursor you pass back to pick up new matches later. Documentation lives inside the app. A credit is one unique job record, and repeat reads of the same record are free. The 7-day trial is 1,400 records. Plans are Kick-off at $79 for 1,000 credits a month, Starter $240 for 5,000, and Growth $480 for 25,000 (less if billed annually), which makes it the most expensive per job here: $79 per 1,000 at entry, $19.20 at Growth.
Python example: job search
# jobspikr_jobs_search.py
import requests
response = requests.post(
"https://api.jobspikr.com/v2/data",
headers={"client_id": "YOUR_CLIENT_ID", "client_auth_key": "YOUR_CLIENT_AUTH_KEY", "Content-Type": "application/json"},
json={
"size": 10,
"format": "json",
"search_query_json": {"bool": {"must": [
{"query_string": {"default_field": "job_title", "query": "\"software engineer\""}},
{"query_string": {"default_field": "inferred_city", "query": "Chicago"}},
{"query_string": {"default_field": "inferred_country", "query": "\"United states\""}}
]}}
}
)
data = response.json()
first = data["job_data"][0]
print(data["total_count"], data["size"], data["job_credit_remaining"], first["job_title"], first["company_name"], first["inferred_city"], first["post_date"], first["job_board"])
Response (trimmed)
{
"status": "success",
"total_count": 1146,
"job_credit_remaining": 1390,
"next_cursor": 1786338381488871,
"job_data": [{
"job_title": "Senior Security Software Engineer, IAM - Moveworks",
"company_name": "Moveworks",
"inferred_city": "Chicago",
"inferred_state": "Illinois",
"post_date": "2026-08-09",
"has_expired": false,
"job_type": "Full Time",
"salary_offered": "USD 137795 - USD 157480 year",
"job_board": "Experteer",
"url": "https://us.experteer.com/career/view-jobs/senior-security-software-engineer-iam-moveworks-chicago-il-usa-...",
"job_description": "..."
}, ...]
}
24 fields, raw and normalised values side by side (city and inferred_city), plain and HTML descriptions, and the credit balance in every response. The ML fields the schema documents (inferred salary, skills, seniority) were absent on the trial; the pricing page lists them under Growth. Median 1.0 s.
Pros
- +Resumable cursor feed, expired-jobs endpoint, and unique-record billing
- +Global, multi-language coverage with normalised location and company names
Cons
- -$79 per 1,000 jobs at entry, the highest here, with enrichment held back for higher tiers
- -Docs only inside the app, prices published as images
Careerjet Job Search API
Best for: publishers who will show Careerjet listings on their own site
Part of Careerjet's publisher program: you register a website, get one key per site, and earn a revenue share when visitors click through. One endpoint, GET /v4/query, with keywords, location, contract type, sort, and page size across 68 locales. Every call must include the end user's IP and user agent plus a Referer header, and your server IP has to be declared first or you get a 403. No prices or quotas are published.
Python example: job search
# careerjet_jobs_search.py
import requests
response = requests.get(
"https://search.api.careerjet.net/v4/query",
params={
"locale_code": "en_US",
"keywords": "software engineer",
"location": "Chicago, IL",
"page_size": 10,
"user_ip": "203.0.113.10", # the end user's IP, required
"user_agent": "Mozilla/5.0" # the end user's browser UA, required
},
auth=("YOUR_API_KEY", ""), # API key as username, empty password
headers={"Referer": "https://www.openwebninja.com/"} # required
)
data = response.json()
first = data["jobs"][0]
print(data["hits"], data["pages"], len(data["jobs"]), first["title"], first["company"], first["locations"], first["date"])
Response (trimmed)
{
"type": "JOBS",
"hits": 915,
"pages": 46,
"jobs": [{
"title": "Sr Software Engineer Low Latency",
"company": "Software Guidance & Assistance",
"locations": "Chicago, IL",
"date": "Fri, 14 Aug 2026 02:04:46 GMT",
"description": "<b>Software</b> Guidance & Assistance, Inc., (SGA), is searching for a Sr <b>Software</b> <b>Engineer</b> Low...",
"salary": "",
"url": "https://jobviewtrack.com/v2/nUIPN0jOL0g1WFFZlKFbcyyP-kl0jTyqtl9DOtedH_Krr4E0KlAtCwkppocQuHlqpcLklLWoLYYrXtez3..."
}, ...]
}
8 fields: a highlighted excerpt instead of a description, no job ID, no employment type, and a jobviewtrack.com redirect URL. Salary fields appear only when a posting states one. The documented page_size was ignored (20 came back regardless) while the legacy pagesize worked. Fastest in the test at 0.4 s median.
Pros
- +Fastest response and no metered cost; the publisher model pays you
- +Hit count on every response and 68 locales
Cons
- -Thinnest record (8 fields), excerpt only, redirect links
- -Built for displaying listings, not pipelines: IP allowlist, end-user IP and UA, Referer on every call
Job Posting API Unit Economics: Cost per 1,000 Jobs
Entry paid plan and the lowest listed rate. Per-request APIs converted at 10 jobs per request.
| API | Billing unit | Entry | At scale |
|---|---|---|---|
| JSearch | Request (up to 10 jobs) | $0.25 | $0.04 |
| SerpApi | Search (10 jobs) | $2.50 | $0.20 |
| Fantastic.jobs | Job returned | $4.75 | $1.80 |
| Coresignal | Job collected (search free) | $19.60 | $0.50 |
| TheirStack | Job returned | $32.67 | $1.10 |
| JobsPikr | Unique job record | $79.00 | $19.20 |
| Adzuna | Request, rate limited | $0 | $0 |
| Careerjet | None (revenue share) | $0 | $0 |
Per-page pricing (JSearch, SerpApi) wins when queries are dense. Per-record pricing (the databases) wins when you filter hard and a query returns three jobs. Coresignal is the hybrid: search free, pay to collect. Adzuna and Careerjet are free but rate limited and return snippets, not descriptions.
Measured Response Time (Same 5 Searches):
Median of the five searches, one request each. Small sample, rough ordering.
| API | Median | Range |
|---|---|---|
| Careerjet | 0.39 s | 0.32 to 0.59 s |
| Adzuna | 0.51 s | 0.47 to 0.93 s |
| JobsPikr | 1.00 s | 0.47 to 1.34 s |
| Fantastic.jobs | 1.04 s | 0.54 to 1.75 s |
| SerpApi | 1.68 s | 0.27 to 8.18 s |
| Coresignal (search) | 2.25 s | 1.74 to 2.73 s |
| TheirStack | 3.43 s | 2.74 to 3.58 s |
| JSearch | 6.30 s | 3.00 to 12.96 s |
Lookups by ID: Coresignal collect 0.15 s, JSearch job-details 5.3 s.
Job Posting API Coverage
| API | Full description | Job by ID | Date and remote filters | Parsed salary | Company or tech data |
|---|---|---|---|---|---|
| JSearch | Yes | Yes | Yes, both | Yes, plus estimates | Tech in details |
| SerpApi | Yes | No | No | When Google shows one | No |
| TheirStack | Yes | No | Yes, both | Yes, annual USD | Yes, both |
| Fantastic.jobs | Yes | Via filter | Yes, both | Yes, plus AI estimate | Yes, both |
| Coresignal | Yes | Yes | Via query DSL | Yes, per source | Yes, both |
| Adzuna | Snippet | No | Date only | Yes, with predicted flag | No |
| JobsPikr | Yes | No | Via query DSL | Raw string | Higher tiers |
| Careerjet | Excerpt | No | No | When stated | No |
The Official Route: Why LinkedIn, Indeed, and Glassdoor Have No Open API
None of them offers an API you can sign up for to read job postings.
- LinkedIn has a Job Posting API for posting jobs, partner-only, and its docs say it is not accepting new partnerships.
- Indeed deprecated its Publisher Job Search API; the remaining partner APIs are for posting and sponsoring jobs.
- Glassdoor says it no longer supports API partnerships. See Glassdoor API alternatives for what to use instead.
- Google Cloud Talent Solution is real but searches jobs you upload yourself. It does not return Google for Jobs listings.
If you want the jobs that appear on those sites, the Google for Jobs APIs see whatever they publish to Google, and the databases crawl career sites and boards directly.
How to Choose: 4 Common Scenarios
A job board or career app
You show live listings to job seekers and need full descriptions, apply links, and filters, at a cost that grows with your traffic.
Best choice: JSearch. Live Google for Jobs results with every apply link, date and remote filters, and job-details and salary endpoints on the same key, at $0.25 per 1,000 jobs. Responses took a few seconds in our sample, so show a loading state. SerpApi returns the same jobs if you already pay for it.
Hiring signals for sales
You track which companies are hiring for which roles or technologies and push that into a CRM or a lead list.
Best choice: TheirStack for technology and company filters with webhooks, or Coresignal for firmographics and a multi-year archive. JSearch keyword queries do a lighter version of the same thing at a fraction of the cost per job.
A daily feed of every new posting
You ingest each new posting once and keep your own database current, so jobs per call and a clean time window matter more than ranking.
Best choice: Fantastic.jobs: time windows, up to 1,000 jobs a call, hourly refresh, $4.75 per 1,000 falling to $1.80. JobsPikr's resumable cursor feed does the same at a higher price, with global coverage.
A prototype or research project with no budget
You want real postings to build on before committing money, and a free key is enough for now.
Best choice: Adzuna: free key, 2,500 requests a month with up to 50 jobs each, salary histograms, 19 countries, but snippets only, and its terms limit commercial use to a 14-day trial. JSearch's 200 free requests and TheirStack's 200 free credits renew monthly and allow a production path.
Pricing Sources
Prices change; check before you commit.
- JSearch: openwebninja.com/api/jsearch
- SerpApi: serpapi.com/pricing, serpapi.com/google-jobs-api
- TheirStack: theirstack.com/en/pricing, API docs
- Fantastic.jobs: developer.fantastic.jobs/pricing
- Coresignal: coresignal.com/pricing, API docs
- Adzuna: developer.adzuna.com/docs/terms_of_service, API docs
- JobsPikr: jobspikr.com/jobspikr-data-pricing
- Careerjet: careerjet.com/partners/api
- LinkedIn, Indeed, Glassdoor, Google: LinkedIn Job Posting API, Indeed Publisher API, Glassdoor API, Cloud Talent Solution
FAQ
Most common questions and answers
Is there a free job posting API?
Is there an official LinkedIn, Indeed, or Glassdoor jobs API?
What is the difference between a Google for Jobs API and a job posting database?
How much does job posting data cost per 1,000 jobs?
Which job APIs return salary data?
Can I look up a single job posting by ID?
Which job posting API is fastest?
Is it legal to collect job postings through an API?
Written by
Adam Ben-Ayoun
CTO at OpenWeb Ninja
Adam leads engineering at OpenWeb Ninja, building the APIs and infrastructure that make public web data accessible to developers and AI agents.
Connect on LinkedInOne key. 50+ APIs. Start free.
200 free JSearch requests a month, no credit card. Live job search, job details, and salary estimates from Google for Jobs, plus SERP, Google Maps, Amazon, and 50+ other APIs on the same key.